Dense vs. MoE Models Explained
Dense models reuse the same network for every token. MoE models choose a few experts from a larger pool. Qwen3.8-27B and Qwen3.8-Flash-Next show why less work per token can still require much more memory.
A model can have more parameters and still do less work to generate each token. That is the idea behind mixture of experts, or MoE.
A parameter is a learned number in a model. A token is a piece of text, often a word or part of a word. As a model processes tokens, it transforms them through a stack of neural-network layers.
The distinction I keep in mind is simple:
- Dense: each token uses the same feed-forward network at each layer.
- MoE: each token uses a few selected feed-forward networks, called experts, at each MoE layer.
That changes how much computation a token needs. It does not make the unused weights disappear.
Researched and updated October 25, 2026. Model specifications below refer to the official open-weight checkpoints, not their hosted API counterparts.
Dense: the same network for every token
Think of a layer as a workshop with two jobs. First, it mixes information from the context. Then a feed-forward network transforms the resulting representation: a list of numbers describing the token at that point.
In a dense model, every token goes through the same feed-forward network at that layer. The values change with the input; the choice of network does not.
Qwen3.8-27B is a dense model. Qwen lists its language model at 27 billion parameters, with 64 layers. Here, “dense” describes the feed-forward architecture. It does not mean every part of the model uses ordinary full attention: this checkpoint mixes Gated DeltaNet layers with gated-attention layers. Qwen3.8-27B model card
Calling it “27B active” is useful shorthand for the dense language network. It is not a literal claim that every stored number is read for every text token: embedding tables use lookups, for example, and a vision encoder serves image inputs.
MoE: choose a few networks for this token
An MoE layer offers several alternative feed-forward networks. A learned router scores them and chooses a small number for the current token. Their outputs are then combined, usually using routing weights.
Top-k routing means selecting k experts. Top-2 selects two. A different token, or the same token at another layer, can select different experts. Mixtral is a straightforward published example: it selects two of eight experts at each layer. Mixtral architecture
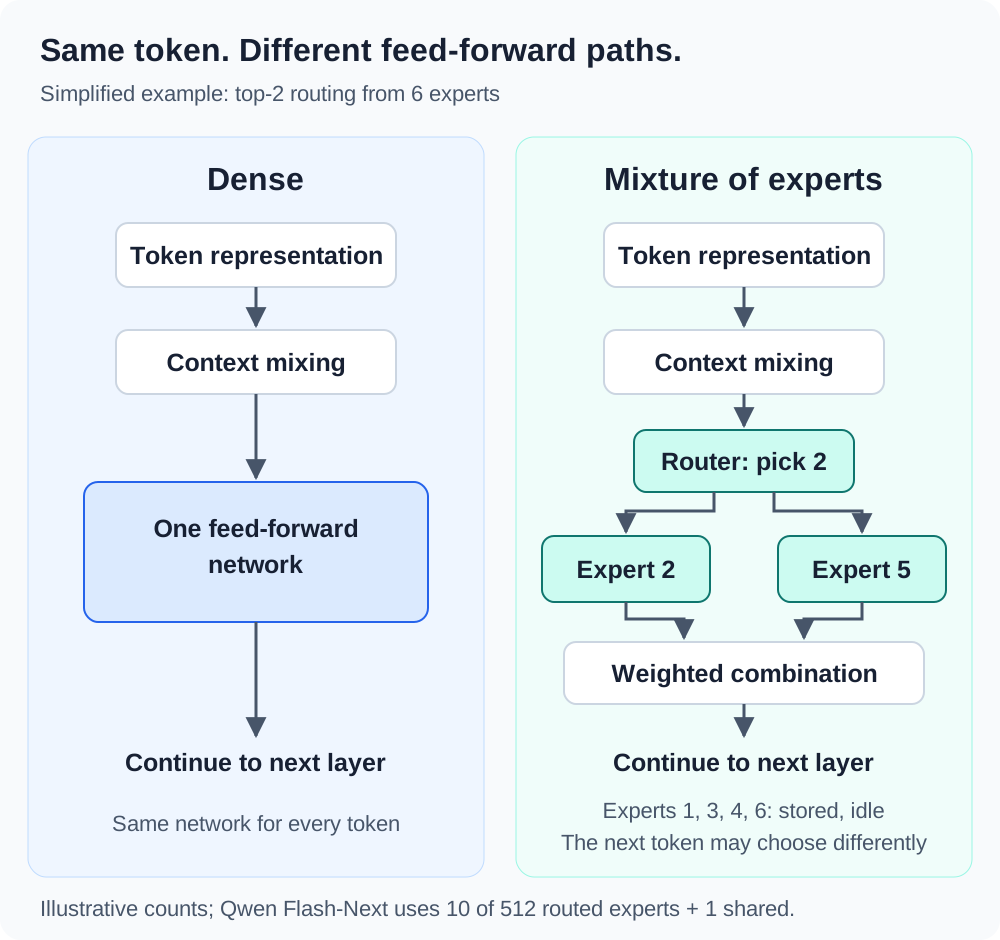
An illustrative top-2-of-6 layer, not the expert counts of either Qwen model. Normalization, residual connections, and other details are omitted.
An expert is a neural-network block inside one model. It receives and returns numbers; it does not write its own answer. The router is not assigning the whole conversation to a separate coding chatbot or math chatbot. In Mixtral, the authors observed routing patterns associated with syntax rather than clear subject boundaries. Mixtral routing analysis
Qwen3.8-27B vs. Qwen3.8-Flash-Next
These checkpoints make the tradeoff concrete:
| Specification | Qwen3.8-27B | Qwen3.8-Flash-Next |
|---|---|---|
| Feed-forward architecture | Dense | MoE |
| Advertised language-model parameters | 27B | 125B, with about 6B activated per token |
| Additional parameter groups listed for Flash-Next | — | 51B n-gram embeddings; 4B multi-token prediction |
| Main language-model layers | 64 | 48 |
| Routed experts available at each MoE layer | None | 512 |
| Experts used at each MoE layer | One dense feed-forward network | 10 routed experts plus 1 shared expert |
Sources: Qwen's 27B model card, Flash-Next model card, and Flash-Next configuration.
The expert counts are per layer. Flash-Next has 48 × 512 = 24,576 routed expert blocks across its main layers. A token selects 10 out of 512 at each layer, alongside a shared expert that always runs. It does not choose just 10 from one global pool of 24,576.
The other important detail is the extra 51B n-gram embedding parameters. These are lookup tables indexed using short token sequences. Qwen's technical report describes keeping these tables in host memory and prefetching the needed entries. They add stored capacity without evaluating a giant feed-forward network for each lookup. The separate MTP, or multi-token prediction, component supports predicting ahead; whether it improves generation speed depends on the runtime and decoding setup. Qwen architecture report
So “125B with 6B active” describes part of the accounting. It is not a complete checkpoint-size estimate, and “6B active” is not a promise of dense-6B speed or memory use.
Stored size and active size answer different questions
Stored parameters help answer: How much space do the weights need?
Active parameters help answer: How much of the network participates in processing one token?
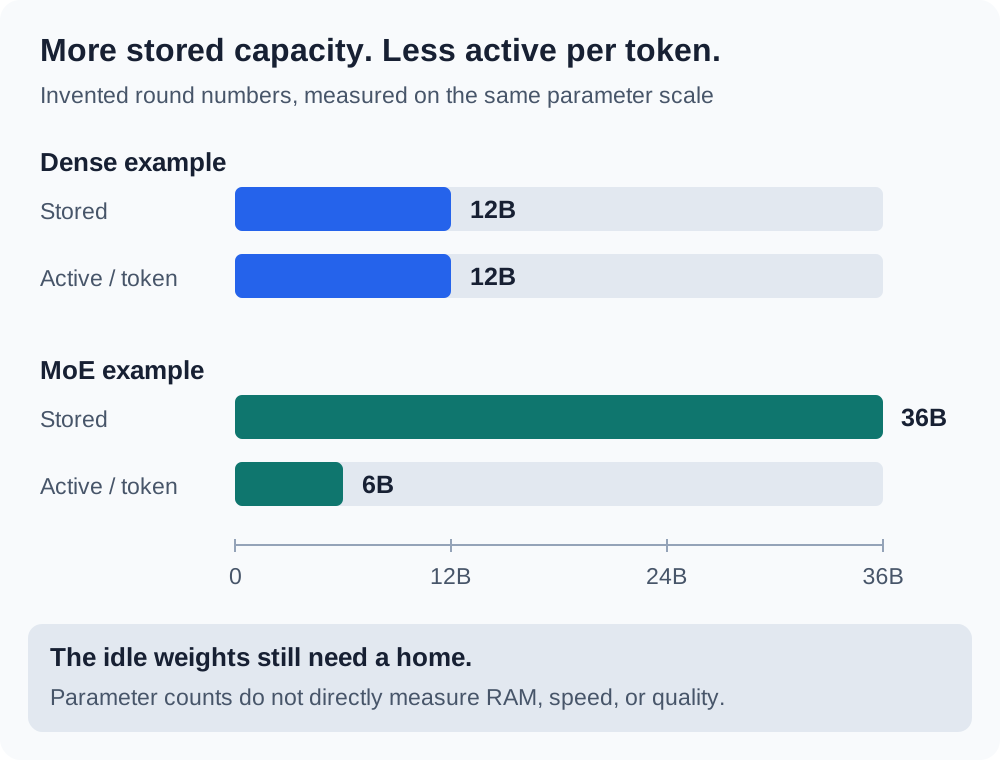
Invented round numbers illustrate the distinction. The bars count parameters; they do not measure RAM, speed, or answer quality.
For a simplified MoE stack with equally sized experts:
stored parameters ≈ shared parameters + all routed experts
active parameters ≈ shared parameters + selected routed experts
Shared experts belong in the shared part. Extra lookup tables and prediction modules need their own accounting. Neither line is an exact formula for execution time.
This is the motivation for sparse conditional computation: increase learned capacity while limiting the work applied to each token. Training also has to keep routing reasonably balanced so a few experts do not receive nearly all the work. The Switch Transformers paper describes this tradeoff and a load-balancing objective.
Memory follows the weights you actually load
The next token may need experts that were idle on the previous one. In an ordinary unpruned deployment, all those weights must remain accessible somewhere: accelerator memory, unified memory, system RAM, or storage.
A useful first estimate is:
raw weight storage in bytes = parameter count × bits per weight ÷ 8
Using only the advertised language-model counts gives:
| Weight group being estimated | BF16: 16 bits per parameter | Hypothetical exact 4-bit storage |
|---|---|---|
| Qwen3.8-27B: 27B | 54 GB | 13.5 GB |
| Flash-Next: 125B portion alone | 250 GB | 62.5 GB |
| Flash-Next: additional 51B n-gram tables | 102 GB | 25.5 GB |
| Flash-Next: additional 4B MTP | 8 GB | 2 GB |
These are calculations from rounded counts, in decimal GB, not measured file sizes or RAM requirements. The listed Flash-Next groups add to roughly 180B parameters: 360 GB at uniform BF16 or 90 GB at hypothetical uniform 4-bit precision. Exact checkpoint contents and quantization choices change the result; a runtime may also omit an optional component.
Real quantized files include scales, metadata, and tensors kept at different precisions. The machine also needs space for attention caches, recurrent state, temporary buffers, and its other software. See LLM Quantization Explained for the storage calculation.
A runtime can keep some weights off the accelerator, fetch them as needed, or compute some operations on the CPU. That reduces accelerator residency by trading against transfers and other work. It does not turn a large checkpoint into a 6B checkpoint. Qwen's architecture report specifically explains the host-memory approach for its n-gram tables.
Why MoE can generate faster
Generation has two phases, covered in Prefill vs. Decode:
- Prefill processes the input prompt, usually working on many tokens together.
- Decode extends the answer, ordinarily one token at a time per conversation. Speculative decoding can propose and verify several tokens together.
For a single conversation with a small batch, decode often spends substantial time moving weights from memory to the compute units. Selecting fewer expert weights can reduce that traffic. That is one reason a larger MoE can generate faster than a smaller dense model.
A deliberately simplified bandwidth estimate is:
seconds per token ≈ bytes transferred per token ÷ effective bandwidth
tokens per second ≈ effective bandwidth ÷ bytes transferred per token
This is a way to understand a bottleneck, not a benchmark. Actual transfers include more than selected expert weights, and cache reuse, quantization, routing, kernel efficiency, and offloading affect the result. Longer contexts and larger batches can change which cost dominates. Efficiently Scaling Transformer Inference
Prefill behaves differently because many tokens can share batched operations. Those tokens may collectively visit much of the expert pool, while each individual token still uses only a subset. MoE retains conditional computation; its realized speed depends on how efficiently the runtime groups the work. Hugging Face's MoE explainer
When experts live on different GPUs, dispatch adds communication too. Tokens travel to the devices holding the chosen experts, and their results return. Interconnect speed and load balance then matter alongside compute. vLLM expert-parallel guide
For these Qwen models, attention also differs: Flash-Next combines Gated DeltaNet with Qwen Sparse Attention, whereas 27B combines Gated DeltaNet with gated attention. A timing comparison therefore measures more than the effect of replacing dense feed-forward networks with experts. Qwen architecture report
Does more total capacity mean better answers?
Parameter counts alone cannot establish that. Training data, training budget, post-training, quantization, and the task all affect the result.
Qwen publishes a comparison of the two checkpoints. Here are three examples, with higher scores better:
| Developer-reported evaluation | Qwen3.8-27B | Qwen3.8-Flash-Next |
|---|---|---|
| SWE-bench Pro | 61.7 | 62.5 |
| DeepSWE 1.1 | 42.2 | 58.7 |
| CoWorkBench | 70.7 | 73.9 |
Source: the Flash-Next model card's language evaluations. These are Qwen's reported results, not my independent measurements. DeepSWE reports the best result across two agent harnesses; CoWorkBench is an in-house evaluation. These comparisons do not isolate MoE as the cause of a score difference or predict a local quantized model's performance.
The varying gaps are useful: one parameter ratio cannot describe the difference across tasks.
What I would compare on my own machine
I would start with the exact checkpoint and quantization, then check:
- Memory headroom: weights, context state, runtime buffers, and the rest of the machine.
- Runtime support: the exact architecture, quantization, offloading strategy, and any MTP acceleration.
- Prompt latency: time to first token with realistic repository and tool context.
- Output performance: decode speed at the context lengths and concurrency I use.
- Useful results: task success, retries, and total time, including any thinking tokens.
Dense models offer a simpler feed-forward execution path. MoE offers a larger pool of learned weights with less selected computation per token, at the cost of storing the pool and managing routing.
For Qwen3.8-27B and Flash-Next, that means keeping three questions separate: Will it fit? How fast does it run? Does it finish my task well? The model name answers none of them on its own.